

With RELY switched on for a new Databricks UNIQUE constraint, our duplicate check returned 0 on a table that held a duplicate key. We found it testing the Public Preview feature on 5 million customers and 50 million orders before recommending RELY to anyone.
The check didn't have a bug. The optimizer rewrote it using the same promise the check was there to verify, so it could only agree. If you turn on RELY to speed up queries, a green daily duplicate check and an orders report that quietly undercounts can arrive together, and nothing in either one looks wrong.
What RELY promises the optimizer
Databricks announced UNIQUE constraints on November 3, in Public Preview for Unity Catalog Delta tables on Databricks SQL and Databricks Runtime 18.2 and above. Like primary and foreign keys, a UNIQUE constraint is informational: Databricks doesn't check it when data is written, so an INSERT with a duplicate key succeeds.
A constraint is NORELY by default, and then it's documentation. Adding RELY tells the optimizer it may trust the constraint. On Photon it then does two things. It drops a DISTINCT or an aggregation when the unique key already makes rows distinct. With RELY on the unique key and on a foreign key that points at it, it also removes a join that can't change the result.
ALTER TABLE customers
  ADD CONSTRAINT customers_uk UNIQUE (customer_id) RELY;

ALTER TABLE orders
  ADD CONSTRAINT orders_customer_fk FOREIGN KEY (customer_id)
  REFERENCES customers (customer_id) RELY;
Databricks says plainly what happens when the data breaks the promise: a rewrite based on the constraint "can produce incorrect results." Its advice is to check for duplicates and orphaned rows first, declare the constraint NORELY, keep the guarantee in your pipelines, and only then switch to RELY. We wanted to see what "incorrect" looks like, and whether the checks that are meant to keep the guarantee would notice.
Wrong counts from one duplicate row
We started small. The customers table had four rows, and two of them shared customer_id 3. The orders table had five orders, two of them for customer 3 and one, order 105, for a customer 9 who doesn't exist. Both constraints went on without complaint, and information_schema.table_constraints showed enforced = NO for both.
Then we ran two queries: how many distinct customers there are, and the row count and total amount of orders joined to customers.
| Constraint mode | Distinct customers | Join rows | Join total |
|---|---|---|---|
| No constraints | 3 | 6 | 170 |
UNIQUE and foreign key, NORELY |
3 | 6 | 170 |
UNIQUE and foreign key, RELY |
4 | 5 | 150 |
Without RELY the answers are right. Customer 3's two orders each match two customer rows, so the join returns six rows, and order 105 drops out because it has no customer. With RELY, EXPLAIN showed a plan that scanned only the orders table. The join was gone, so every order counted once, including the one for the customer who doesn't exist. The distinct count came back without any aggregation, as a plain count of rows.
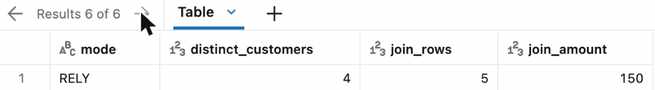
One thing nearly fooled us here. The first run after we added RELY still returned 3, 6 and 170, because Databricks served it from the query result cache. Only after SET use_cached_result = false did the wrong numbers appear.
The duplicate check that the optimizer rewrote
Next we asked the obvious question: would our usual checks catch the duplicate while RELY was on? We ran the queries most of us write without thinking, on the same small tables.
-- Both return 0 while RELY is on, on a table with a duplicate key
SELECT COUNT(*) FROM (
  SELECT customer_id FROM customers
  GROUP BY customer_id HAVING COUNT(*) > 1
);

SELECT COUNT(*) - COUNT(DISTINCT customer_id) FROM customers;
Both said 0. So did a version that groups by customer_id + 0, which we tried in case the optimizer only recognized the bare column.
Two checks still found the duplicate. A window count, which looks at each row instead of grouping, returned the two rows for customer 3. A DISTINCT count on a cast version of the key also showed one duplicate.
-- Still catches it with RELY on: returns 2 rows for customer_id 3
SELECT COUNT(*) FROM (
  SELECT customer_id, COUNT(*) OVER (PARTITION BY customer_id) AS n
  FROM customers
) WHERE n > 1;
The orphan checks for the foreign key kept working. Both a LEFT ANTI JOIN and a NOT IN query found the orphan order.

This surprised us more than the wrong counts. Databricks tells you to keep validating the guarantee after you switch to RELY, and the two checks we'd normally schedule for that job both said 0.
A late duplicate on 50 million orders
The small tables show the mechanism. The more realistic failure is clean data that goes bad after RELY is on. We built 5 million customers and 50 million orders, every order pointing at a real customer, and declared both constraints. While they were NORELY, the duplicate and orphan checks returned 0 and 0, and the data really was clean.
We switched both constraints to RELY. Then we inserted customer 42 a second time, the way a retried load or a re-sent file would. The INSERT succeeded, because nothing checks the constraint on write. Customer 42 has five orders.
| State | GROUP BY check | COUNT DISTINCT check | Window check rows | Join rows |
|---|---|---|---|---|
RELY, after the late duplicate |
0 | 0 | 2 | 50,000,000 |
Same data, NORELY |
1 | 1 | 2 | 50,000,005 |
With RELY on, the GROUP BY duplicate check returned 0 and the join lost the five extra rows that customer 42's second record should have produced. Both numbers came out too low: the check missed one duplicate key, and the join missed five rows.
The left path is what happens with the usual checks. Once RELY is on and a late duplicate is inserted, the daily GROUP BY check runs, the optimizer trusts the promise, the check reports 0 duplicates, and the next report runs with the join removed and misses 5 rows. On the right, the window count check sees 2 rows for one key, and raise_error stops the pipeline before anyone reads the numbers.
What RELY saved and what checking costs
We also measured whether RELY was worth it. On a 2X-Small serverless SQL warehouse with the result cache off, we ran each query three times and read the runtime the SQL editor shows.
| Query on 5M customers, 50M orders | NORELY |
RELY |
|---|---|---|
| Orders joined to customers, count and sum | 1.11 s, 1.10 s, 1.01 s | 0.73 s, 0.63 s, 0.75 s |
| Count of distinct customers | 0.70 s, 0.70 s, 0.75 s | 0.57 s, 0.60 s, 0.58 s |
EXPLAIN confirmed the join was gone entirely under RELY. The gain is real, about 0.35 seconds on the join, but modest at this size, and we didn't measure larger tables.
The guard costs more than that. Our combined duplicate and orphan check took 1.2 seconds on the same tables. Running it before every query would eat the whole saving, so we'd run it as a pipeline step right after the write, where it fails loudly:
SELECT CASE
  WHEN dup_rows > 0 OR orphans > 0 THEN raise_error(
    concat('RELY check failed: ', dup_rows, ' duplicate rows, ',
           orphans, ' orphan orders'))
  ELSE 'ok'
END AS rely_check
FROM (
  SELECT
    (SELECT COUNT(*) FROM (
       SELECT COUNT(*) OVER (PARTITION BY customer_id) AS n FROM customers
     ) WHERE n > 1) AS dup_rows,
    (SELECT COUNT(*) FROM orders o
       LEFT ANTI JOIN customers c ON o.customer_id = c.customer_id) AS orphans
);
Where we would turn RELY on
We'd turn RELY on only where the pipeline itself guarantees the key, such as a MERGE on the key, which updates the existing row when the same change arrives twice, or a Lakeflow pipeline that applies a source's change data capture (CDC) feed of inserts, updates and deletes through AUTO CDC and keeps only the latest row for each key. For append-only tables without deduplication, we don't recommend RELY, because the first retried load turns a speed-up into a wrong report. Validate duplicates and orphans while the constraint is NORELY, then switch, and keep a check that can't be rewritten in the pipeline. We fed our guard a known duplicate and watched it fail before trusting it, the same approach as testing data quality rules against known defects.
If RELY is already on somewhere in your workspace, start by listing those tables from information_schema.table_constraints and running the window duplicate check on each. Then ask whether the pipeline that writes each table really guarantees the key. Where it doesn't, go back to NORELY until it does, and put the failing check in front of your release gate.
Frequently asked questions
Does Databricks enforce UNIQUE constraints?
No. UNIQUE, primary key and foreign key constraints are informational, so a write that breaks them succeeds. In our test, adding a RELY constraint to a table that already held a duplicate key worked without an error. Enforcement has to come from your pipeline, for example a MERGE on the key or a deduplication step.
What does RELY do on a Databricks constraint?
RELY lets the optimizer use the constraint to rewrite queries. On Photon that means removing a DISTINCT or aggregation over a unique key, and removing a join when both the unique key and the foreign key are RELY. Without RELY, the constraint is metadata only and query results don't depend on whether the data matches it.
How do I check for duplicates when RELY is on?
Use a query that looks at individual rows, such as a window COUNT(*) OVER (PARTITION BY key) filtered to counts above 1. In our tests a GROUP BY ... HAVING COUNT(*) > 1 check and a COUNT(*) - COUNT(DISTINCT key) check both returned 0 under RELY with a duplicate present. The safer habit is to run the full validation while the constraint is NORELY, before switching it on.
Can I switch a constraint from RELY back to NORELY?
Yes. We dropped the constraints and added them again with NORELY, dropping the foreign key before the unique key it references, and the next queries returned the correct counts. Turn the result cache off when you compare before and after, or you may be looking at an answer computed under the old setting.