

A nightly Databricks job fails after its write commits, the scheduler retries it, and the next morning's revenue report counts the same orders twice. Backend engineers know this bug from message handlers that process a message twice, and on a lakehouse it's fixed the same way.
As a .NET engineer at TechFabric who now also works on Databricks, I found that most backend habits carry over and a few assumptions don't. Nothing says which ones until a job runs twice or a table changes overnight.
A team that carries the right habits over keeps its reports correct after a retry, and undoes a bad write the same day instead of paying for a rebuild and explaining wrong numbers to customers. The habit that carries over most directly is the one backend teams already guard hardest, the contract.
Habits that carry over from application work
Contracts and explicit schemas
In a service, the API contract is what you protect, and a Delta table plays the same role for every job and report that reads it. Databricks enforces the schema on write for Delta tables, so an INSERT that names a column the table doesn't have fails, and schema evolution is something you switch on deliberately, for example with the mergeSchema write option or an explicit ALTER TABLE. One detail is easy to miss. A MERGE with UPDATE SET * and INSERT *, like the one below, requires the source to have every target column, and Databricks ignores source columns the target table doesn't have.
A schema change deserves the handling a breaking API change gets, with a review and a note to the consumers before it ships. Column descriptions in Unity Catalog are part of that contract too. They're what the next engineer reads to learn what a column means, and Databricks calls quality column descriptions in Unity Catalog critical for Genie accuracy.
Idempotency and retries
Jobs fail and get retried, the same way message handlers do, and a job can fail after its write commits. A handler that writes two rows for one message is a bug, and so is a job that appends the same batch twice. The fix is the one backend engineers already use, which is to key the write so running it again lands on the same rows.
MERGE INTO orders AS t
USING staged_orders AS s
  ON t.order_id = s.order_id
WHEN MATCHED THEN UPDATE SET *
WHEN NOT MATCHED THEN INSERT *;
When the scheduler retries the job, a plain INSERT appends the batch again, and the duplicate orders show up in the next report. A MERGE matches rows on order_id instead. We ran this MERGE twice on a small demo table. Each run committed a new table version. The first updated one row and inserted one, the second rewrote the two matched rows and inserted nothing, and the table held three orders after both runs.
Versioning and rollback
Backend teams version their deployments and know how to roll one back. Delta tables keep versions too, since every commit creates one, and RESTORE takes a table back to a previous version when a bad write lands. Jobs and pipelines are code as well, and Declarative Automation Bundles (formerly Databricks Asset Bundles) describe them as source files, so they can go through the same source control and code review as a service.
Tests for transformations
A transformation is code, and it deserves tests like code. What changes is what the tests assert on, which is row counts, nulls, freshness and distributions as well as return values. For checks that hold back a release, see Databricks Data Quality Gates: From Failed Checks to Blocked Releases, and for testing the checks themselves, Testing the tests: a kill matrix for Databricks data quality rules.
Assumptions that break on a lakehouse
Query cost on pay-per-use compute
On a lakehouse an inefficient query costs money every time it runs. Cost belongs in the design review next to correctness, before the job is scheduled.
Writes across several tables
Backend engineers are used to wrapping several writes in one transaction. On Databricks, by default each SQL statement executes as its own atomic transaction against one table, so a pipeline that updates three tables in three steps makes three commits, and a failure halfway through leaves the first table ahead of the others. Databricks also supports transactions across several tables, but only on Unity Catalog managed tables with catalog commits enabled, so a pipeline over any other tables still needs the same design as a distributed system. Each step has to be safe to rerun, which in practice means keyed writes like the MERGE above rather than appends, and downstream readers have to tolerate a table that's one step ahead of its neighbours, for example by reading from the last table in the chain only after the run that feeds it has finished.
Where state lives
In an Orleans grain, state is loaded from a configured storage provider when the grain activates and written back when the grain calls WriteStateAsync. On a lakehouse the job is disposable and the table holds the state. When a number is wrong, a write to a table is a common cause, and the table's history is a good place to start the investigation.
Debugging with table history
In a service, debugging usually starts from logs and traces.
On Databricks the first question is usually what changed in the table, and when. The DESCRIBE HISTORY command answers it with the operations, user and timestamp for each write to the table.
SELECT version, timestamp, operation, operationParameters
FROM (DESCRIBE HISTORY orders)
ORDER BY version;

RESTORE TABLE orders TO VERSION AS OF 3;
On the demo table, the history showed the create (version 0), the first insert (version 1), the two MERGE runs (versions 2 and 3) and a DELETE with the predicate status = new (version 4). That DELETE removed two of the three orders. Restoring to version 3 brought them back and added version 5, a RESTORE that records which version it went back to.
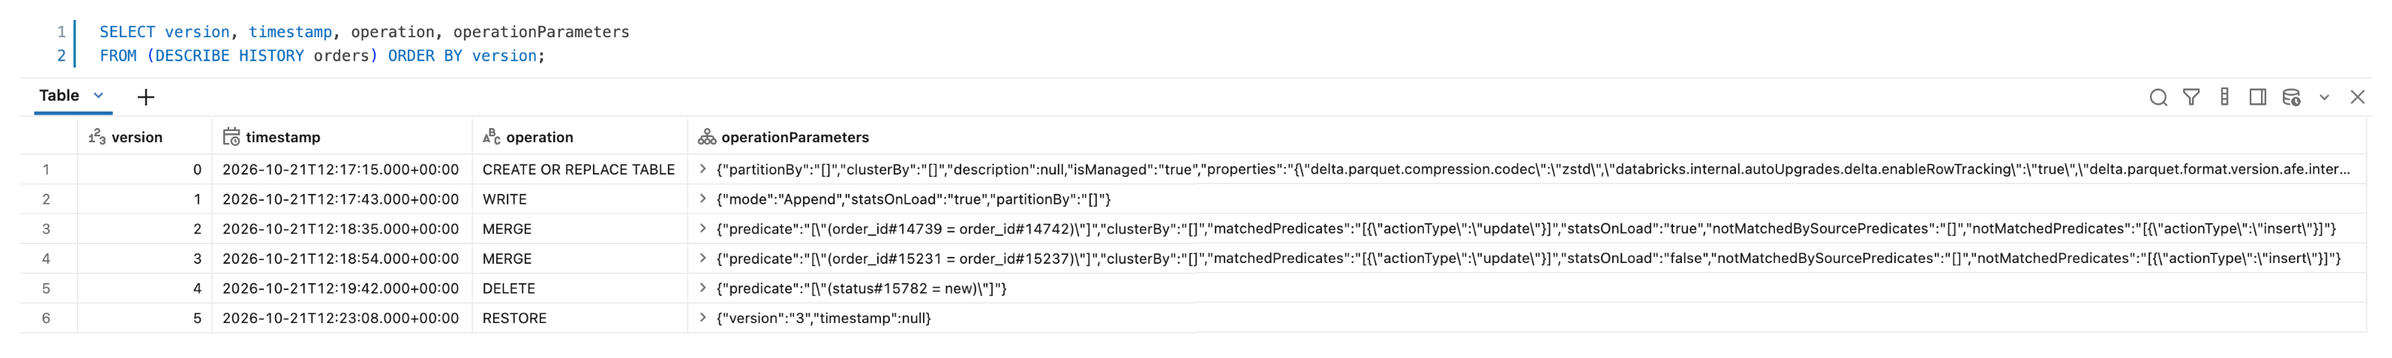
Event-sourced systems teach the same skill. Chasing a bad event through a stream and reading a table's history to find the write that went wrong are the same work against a different store. RESTORE only reaches versions whose files are still within the table's retention period, so a bad write found weeks later may be past it.
Build one small pipeline end to end first
In my experience the Databricks certifications give an engineer the vocabulary, not the experience. The experience comes from one small project that ingests something, models it and serves it to a person, because the gaps show up at the seams between those steps.
A Genie Agent (formerly a Genie space) over data the engineer already knows well is a good first project, since its accuracy depends on the column descriptions and metric definitions the engineer writes, as the Genie best practices spell out.
Frequently asked questions
Which backend habit pays off first on Databricks?
Idempotent writes. Jobs get retried, and a keyed MERGE instead of a plain append decides whether a retry changes nothing or duplicates a day of data. It's also the cheapest habit to adopt, because it's one statement in the job.
How do I find out what changed in a Delta table overnight?
Run DESCRIBE HISTORY on the table. It returns the operations, user and timestamp for each write to the table, with the version each write created. Within the table's retention period you can query an earlier version with VERSION AS OF and bring it back with RESTORE TABLE.
Does a second run of the same MERGE change the table?
It changes the history but not the data. The second run commits a new version and can rewrite the matched rows, but the rows it writes are the ones that were already there, so row counts and values stay the same.